#compliance
Compliance Monitoring in 2026: Know What Is Working
Your access policy says former employees lose production access promptly. The tickets are closed. But an account review...
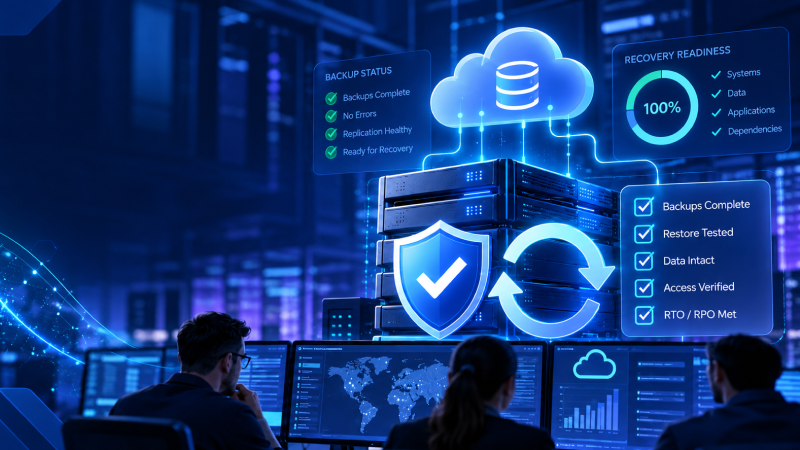
The backup dashboard is green. A customer asks how quickly a critical service can be restored after an outage. The team finds the latest backup, but no record of a successful restore. The backup exists; the answer is still uncertain.
That gap is why backup compliance needs more than a schedule and a screenshot. Security and compliance teams need to know which services are protected, how much data could be lost, how long recovery could take, whether the backup survives a cyber incident and what happened during the last test.
This backup checklist works through three practical questions: What should be backed up? How often should it run? How can you prove recovery works? It is designed for teams managing ISO 27001, SOC 2 or other relevant assurance needs in 2026.
Start with the business service, not just its main database. A customer application may depend on application data, identity settings, infrastructure configuration, encryption keys, certificates and integrations. Restoring yesterday’s database will not bring the service back if the team cannot rebuild its environment or recover the secrets needed to start it.
List the components needed to restore each important service. Record where each one is protected and who can perform the recovery. Common categories include:
Not every component needs the same type of backup. A repository may already have a controlled recovery mechanism. A managed service may offer snapshots but require you to enable or configure them. A SaaS contract may define what the provider restores and what remains the customer’s responsibility. Check those arrangements rather than assuming the word “cloud” settles the question.
The most useful output is a service-to-backup map. For each critical service, show its important components, backup method, owner, recovery target and last tested result. This makes missing dependencies visible before an incident.
There is no single schedule that fits every organization and every system. Decide frequency from the impact of losing recent data and from any specific obligation that applies. The recovery point objective (RPO) is the point in time to which data needs to be recovered after an outage. If the approved RPO is four hours, the protection method must be capable of meeting that target under the expected failure conditions.
The recovery time objective (RTO) addresses how long the service can be in recovery before the disruption causes unacceptable harm. RPO and RTO answer different questions. Frequent backups can reduce potential data loss, but they do not guarantee a quick restore.
Consider two services. A billing platform that changes throughout the day may have a short RPO and require frequent snapshots or another suitable recovery method. An archive updated once a week may tolerate a longer interval. These are examples, not default schedules. The business owner and recovery team should agree on acceptable loss and downtime, then test whether the chosen design meets them.
Backups can also fail between scheduled runs. If an hourly job fails for half a day and no one notices, the latest usable copy may fall outside the RPO. Measure the age of the last successful, usable recovery point, not just the interval configured in a policy.
Use the questions below to review a service with its owner and backup operator. An unchecked answer becomes an action, with an owner and a date.
| Check | Question the team should answer | Useful evidence |
|---|---|---|
| Scope | Do backups cover each component needed to recover the service? | Service inventory mapped to backup jobs or other recovery methods |
| Frequency | Can the most recent usable copy meet the approved RPO? | Schedules, successful run history and recovery point age |
| Retention | Are copies kept for the period the organization needs? | Approved retention setting and actual recovery points |
| Protection | Could one compromised administrator delete production and every backup? | Access rights, separation, offline or immutable copy settings |
| Monitoring | Does someone learn when a job fails or a source stops reporting? | Alerts, review records and assigned follow-up |
| Restore | Can the team recover the data and the service within the intended window? | Restore test, result and measured recovery time |
| Change | Is backup coverage checked when a new system or data flow is added? | Change record, owner review and updated scope |
A backup job may pass one check and fail another. For example, it may complete every night but omit a newly created storage location. Treat coverage, job health, protection and restore results as separate questions.
Recovery copies need protection from accidental deletion and malicious change. Ransomware can target online backups and the credentials that administer them. For critical data, consider an offline copy, immutable storage or another protected copy appropriate to the environment. Restrict who can change retention, delete recovery points or disable jobs. Protect backup credentials and encryption keys.
Test the isolation assumption. If the same account can administer production and remove every backup, one compromised account can defeat the recovery plan. A separate storage location alone may not help if the same permissions follow it.
A successful backup job shows that the job ran. A restore test checks whether the copy can be used. Start with one service and define the scenario: a deleted file, a failed database, a compromised server or a whole service unavailable. Pick a scenario that exercises the dependencies that matter.
Record the recovery point chosen, the person running the test, the environment used, the time taken and whether the restored data was correct. A technically completed restore is not enough if an application cannot read the data, a required identity configuration is missing or the result exceeds the RTO.
Tests should fit the importance and complexity of the service. A file-level restore may be appropriate for a narrow check. A critical service also needs an exercise that shows its components work together. When a test fails, identify the cause, assign a fix and repeat the relevant check. Keep the failed result in the record so the improvement can be traced.
Do not assume a fixed six-month test interval is required by every framework. Set a risk-based schedule, follow applicable obligations and test again when material changes affect the recovery design.
Start with the requirement and its scope. For an ISO 27001 information security management system, the organization selects necessary controls through risk treatment and documents them in the Statement of Applicability. Backup is addressed in Annex A control 8.13 of the current edition. For SOC 2, the evidence should match the system, selected criteria and examination period. A regulator or contract may add specific expectations.
Useful backup audit evidence shows four things together: the intended scope, the actual backup runs, how failures were handled and what happened in a restore test. It should have dates, named owners and links to the service or assets concerned.
A screenshot of a scheduled job can show configuration at one moment. It does not establish that every expected job ran throughout a period or that the data was recoverable. A better evidence trail connects the backup inventory to job history, alerts, tickets, restore tests and closure of exceptions.
Avoid promising a 100% job success rate as if every missed run were automatically a failed audit. The meaningful question is whether failures were detected, investigated and resolved in time to meet the organization’s recovery needs. Show the gap and the response honestly.
A new service is never added. An application owner deploys a new database, but its backup job is not in the original plan. Include backup coverage in onboarding and change reviews.
The job runs, but no one can restore the service. A restore test uncovers missing keys or configuration. Keep recovery dependencies in the service map and retest after the fix.
A failed job sits unseen. Alerts reach a mailbox with no clear owner. Give critical failures a response target, an escalation route and a way to confirm a usable recovery point exists.
Copies share the same weakness. One compromised identity can remove production data and every available backup. Review permissions, storage separation and protected copies.
Evidence is assembled at the last minute. The team has job logs but cannot tell which assets they cover or which failures were accepted. Connect the records during normal operations, not only when an audit begins.
Backup operations often sit in one system while the service inventory, incidents and risk decisions sit elsewhere. SPOG.AI’s continuous control monitoring approach connects defined controls to operational evidence so teams can see coverage, failed checks and follow-up across connected systems. Its governance and risk capabilities can relate those results to assets, owners, exceptions and remediation.
For a backup control, that means asking whether each critical service has the intended protection, when the last usable copy was created, what failed and who is fixing it. The backup and recovery tools still perform the jobs and restores. A connected control view helps the team understand whether the coverage and evidence support the decision it needs to make.
In 2026, the practical standard is simple: know what you must recover, set targets that reflect the business, protect the recovery copies and demonstrate that a restore worked. If a service cannot pass that test, the next step is an owned action, not a green dashboard.
Your access policy says former employees lose production access promptly. The tickets are closed. But an account review...
A SaaS company can have strong security practices and still struggle to answer a customer’s questionnaire. The team...
Your company already has an identity tool, a cloud platform, endpoint protection and a ticketing system. Yet when...