Cybersecurity Risk Scoring: Make the Score Decision-Ready
A cybersecurity risk score should explain why an exposure matters and what action it requires. Learn how to combine threat signals, reachability, business impact and control evidence into clear priorities, while keeping uncertainty and accountability visible.
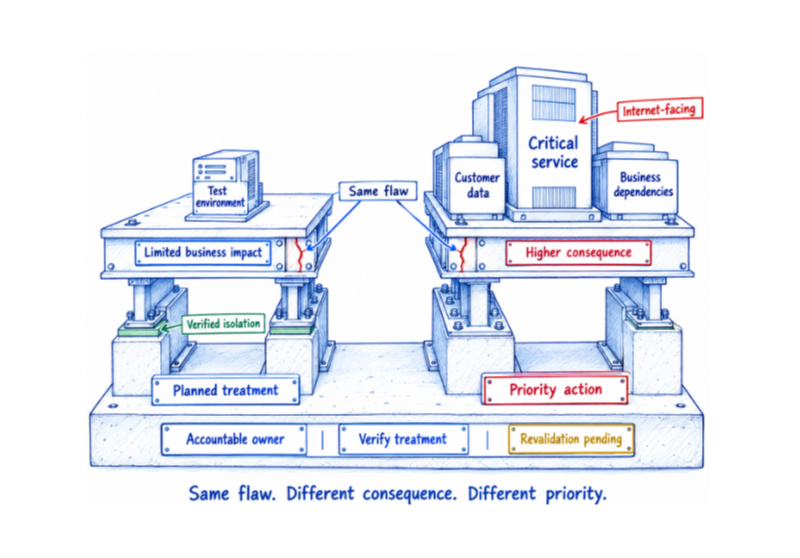
Two vulnerabilities can have the same severity score and deserve very different decisions. One sits behind strong controls on an isolated test system. The other is exposed to the internet, affects a critical service and has a documented path to privileged access. Cybersecurity risk scoring is useful only when it helps leaders see that difference and gives teams a defensible basis for action.
The goal is not to manufacture a perfectly precise number. It is to make prioritization consistent, explainable and responsive to changing conditions. A strong score combines reliable signals with business context, makes uncertainty visible, and connects the resulting priority to an owner, a decision and a verified outcome.
What cybersecurity risk scoring should answer
Cybersecurity risk scoring is a method for ranking exposures, control gaps, findings or scenarios according to the attention they require. The unit being scored matters. A vulnerability, misconfiguration, identity entitlement, supplier dependency and failed recovery test do not carry the same evidence or decision path. Define the unit first, then define the decision that the score is meant to support.
For an operational team, the question may be which findings must be contained today. For a CISO, it may be which unresolved exposures could materially affect a service or risk appetite. For GRC, it may be whether a control failure creates a residual risk decision. One enterprise score rarely serves all three uses without losing critical detail.
Risk scoring is not the same as predictive analytics
Predictive analytics estimates a future outcome from observed patterns. It can help forecast likely recurrence, workload demand or the probability that a class of findings will grow. Cybersecurity risk scoring may use predictive signals, but it also relies on present conditions: current exposure, asset criticality, privilege, control health, known exploitation and compensating measures.
Treat a prediction as one input, not as a verdict. Models can be useful when they are validated against a clearly defined question and monitored for drift. They cannot reliably infer a business consequence from incomplete asset ownership, stale inventories or unverified relationships. When key context is missing, the score should expose that uncertainty rather than quietly convert it into a low priority.
The four dimensions of a decision-ready score
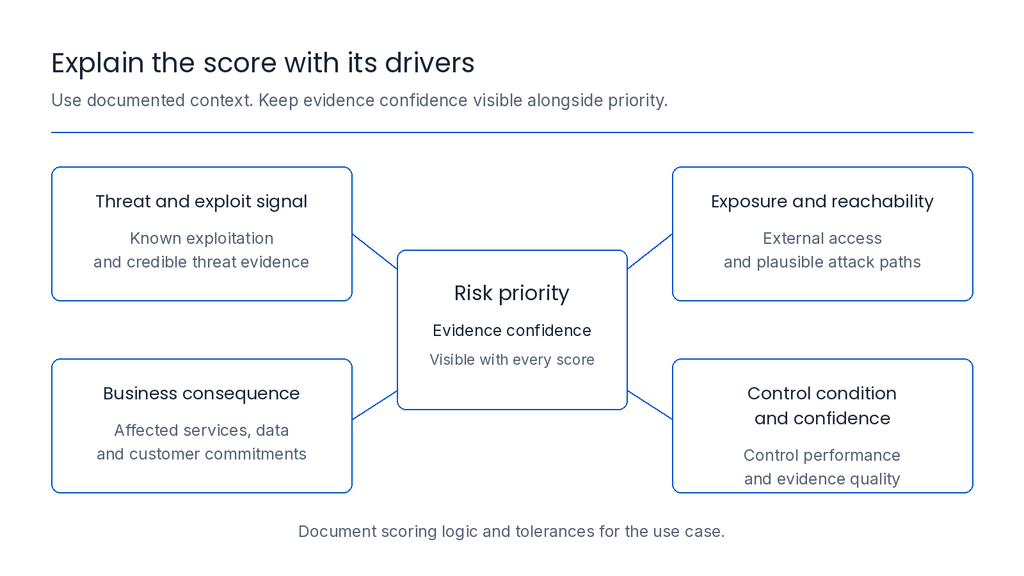
A practical cybersecurity risk scoring model does not need dozens of opaque variables. It needs a small set of dimensions that can be explained to the people who must act and govern the result:
Threat and exploit signal: whether there is credible evidence of exploitation, exploitability or active threat relevance.
Exposure and reachability: whether the condition is externally reachable, accessible through a plausible path or contained by segmentation and other controls.
Business consequence: the criticality of the affected service, data, process or customer commitment.
Control condition and confidence: whether preventive, detective and recovery controls are present and working, and how complete and current the supporting evidence is.
These are not universal weights. A payment platform, hospital system and internal development environment can legitimately apply different tolerances. What matters is that the logic is documented, reviewable and stable enough to compare similar situations fairly.
Design risk scoring so it can be challenged
A score should carry its explanation with it. A resource owner must be able to see the source records, the scoring factors, the time each factor was observed and the reason an item crossed a threshold. Without that evidence trail, teams cannot correct a stale ownership record, dispute an inaccurate reachability assumption or distinguish a real change in risk from a data-quality issue.
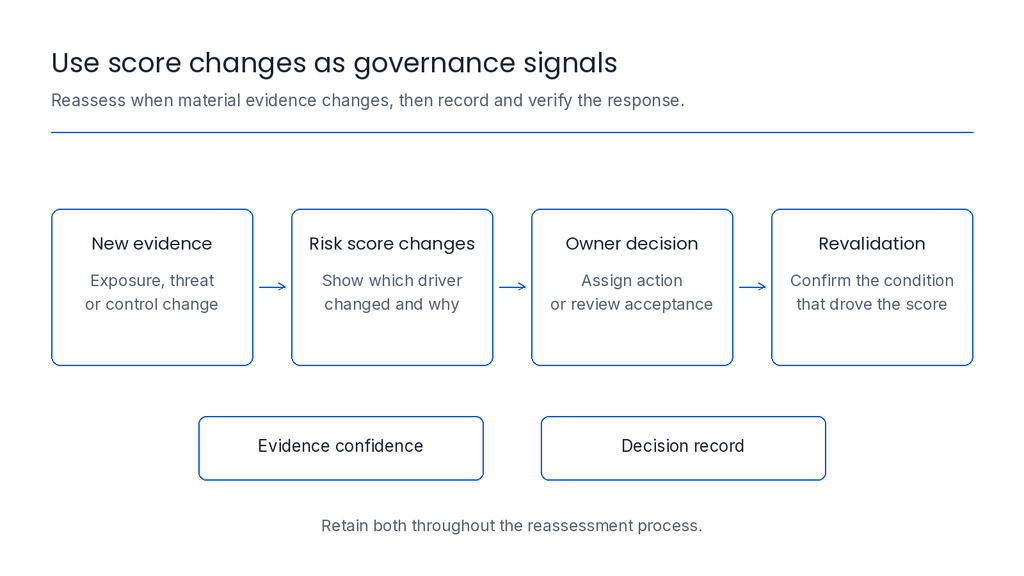
Avoid false precision. A result such as 87.36 can imply confidence the data does not support. Use decision bands only when each band corresponds to a clear action, such as immediate containment, accelerated remediation, planned treatment or accepted residual risk. Preserve the underlying drivers and show which one changed when an item moves between bands.
A simple illustrative scenario makes the point. A newly disclosed flaw on a public-facing administrative service may move to the highest action band because it is reachable, supports a critical process and lacks compensating control. The same flaw on a retired internal asset may require inventory correction before remediation urgency can be determined. The model did not replace judgement; it made the judgement more consistent.
Connect each risk score to an operating decision
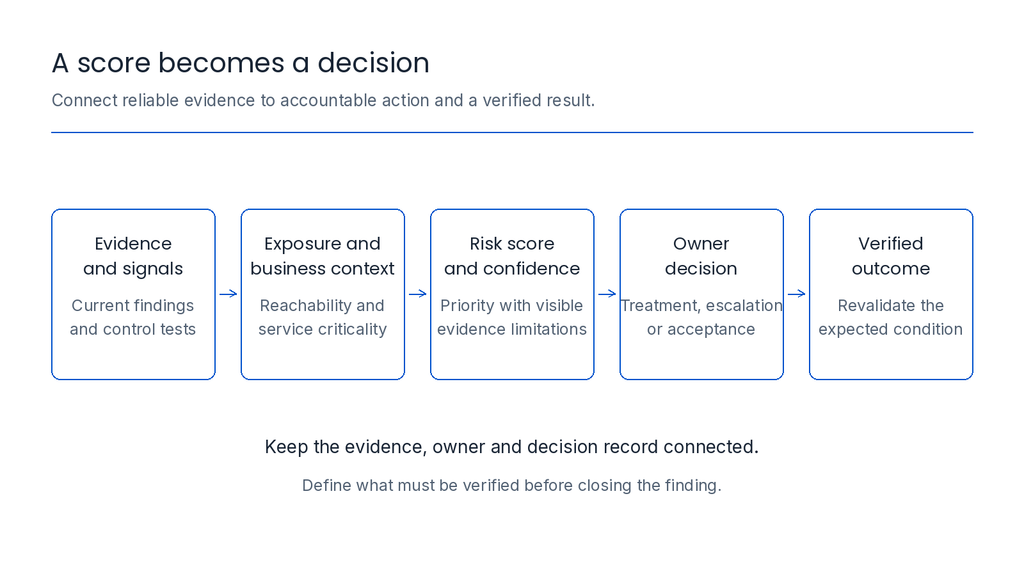
Risk scoring fails when it ends at a dashboard. Each meaningful band needs an owner, response target, escalation route and closure condition. The closure condition should not be ‘ticket completed.’ It should specify what evidence is required to show containment, remediation, risk acceptance or restoration of the expected control state.
This is where continuous control monitoring strengthens the model. A finding can be connected to the control it affects, the expected population, its evidence source, the owner and a follow-up test. That enables teams to show whether action reduced the condition that drove the score rather than simply reducing the number of open tickets.
Build evidence quality into the score
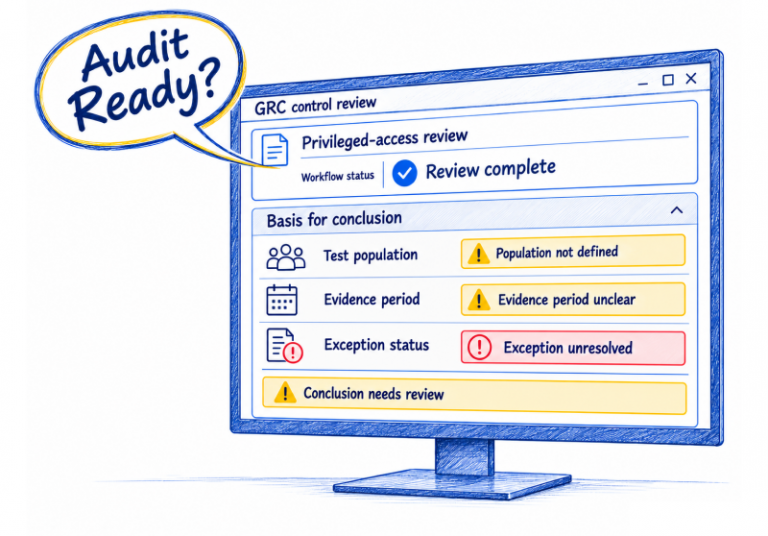
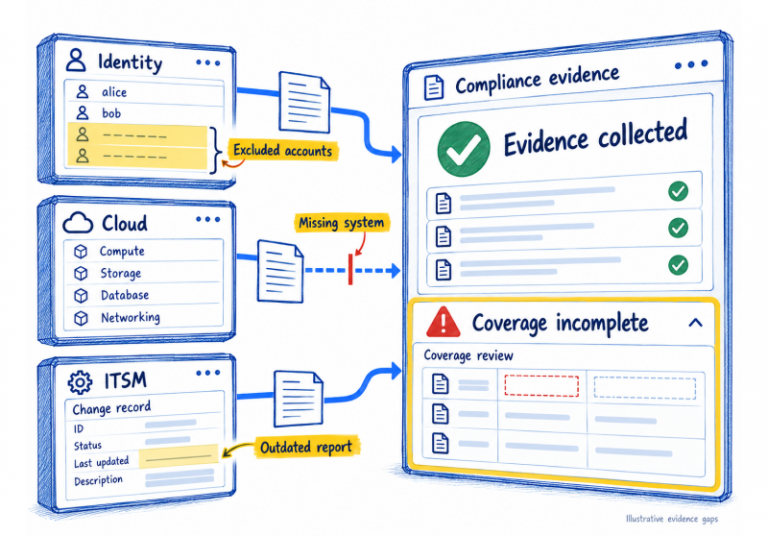
A risk score can be directionally wrong even when its formula is sound if it relies on incomplete data. Record the provenance, collection time and scope of every material input. Asset criticality should come from an accountable service or business record, not an assumed hostname. Internet exposure should be tested against a current view of reachability. A control should be treated as unknown when its evidence source has failed or aged beyond its agreed validity window.
This does not require waiting for perfect data. It requires preventing uncertainty from masquerading as safety. When a high-consequence asset has incomplete ownership or exposure data, route the information gap for investigation and make the confidence limitation visible to the decision maker. That is often more useful than assigning a low score because the required input was absent.
Over time, the pattern of unknown inputs can also identify where the asset inventory, ownership model or control evidence needs investment and sustained executive sponsorship.
Keep the model current without chasing constant change
Review the model whenever the operating environment or decision need changes, not merely on a calendar. New internet exposure, a material acquisition, a change in critical service ownership or evidence that a threat is being exploited may justify immediate reassessment. Less volatile inputs can be reviewed on a defined cadence.
Separate model monitoring from individual finding updates. Model monitoring asks whether the score continues to prioritize the right work across the portfolio. Review the distribution of items across action bands, frequent overrides, evidence gaps, reopened issues and outcomes after remediation. A growing number of manual overrides is a sign to refine the logic, data or governance, not simply to override more often.
How SPOG.AI supports risk-informed prioritization
SPOG.AI’s governance, risk and compliance approach connects requirements, controls, operational evidence, ownership and exceptions across existing systems. That shared context can help teams relate a finding to an affected service, document a risk decision, assign remediation and reassess the result as evidence changes. Security, IT and GRC teams still define their own risk tolerance, approval authority and response decisions.
Start with a single high-consequence use case, such as internet-facing vulnerability prioritization, privileged-access exceptions or cloud configuration drift. Define the decision, evidence, action bands and verification step. Once the score produces a trusted operating decision, expand the model carefully to adjacent risk types.
Conclusion
Cybersecurity risk scoring should make a difficult decision easier to explain, not hide it behind a number. Build the score around current evidence, exposure, business consequence and control condition. Give every significant result an accountable response and a revalidation step. The result is a prioritization method that can evolve with the environment while remaining useful to the people who must decide and act.
Frequently asked questions
What is cybersecurity risk scoring?
It is a repeatable way to rank exposures, findings or risk scenarios by the attention and action they require, using documented evidence and business context.
Is a severity score the same as a risk score?
No. Severity describes characteristics of an issue. A risk score should also account for exposure, business consequence, control condition and uncertainty.
Can predictive analytics improve risk scoring?
Yes, as a validated input for a defined question. It should not replace current evidence, business context or accountable human decisions.
Which factors should a cyber risk score include?
Common factors include threat or exploit signal, reachability, asset or service criticality, data sensitivity, privilege, compensating controls and evidence confidence.
How many risk bands should an organization use?
Use only as many as are needed to trigger distinct actions. Each band should have an owner, response expectation and escalation path.
How do you avoid false precision?
Show the score drivers, evidence, time and confidence. Use clear action bands instead of presenting decimals that imply unsupported certainty.
Who should approve a risk-score override?
The accountable owner should be able to challenge source data, while material overrides and exceptions should follow the organization’s documented approval authority.
How often should risk scores change?
Update when material evidence changes and review model performance on a defined cadence. Do not refresh scores without understanding whether the inputs are current.
How do you know remediation reduces risk?
Reassess the condition that drove the score, confirm the expected control state and retain evidence of the verified outcome.
What should leaders see in a risk-scoring report?
They need material items by action band, major score drivers, evidence of confidence, aging decisions, exceptions, verified outcomes and trends that explain what changed.
Technology writer and content strategist with 5+ years of experience, including work for a US-based B2B SaaS client and a cybersecurity solution. I create cybersecurity and GRC content, product documentation, and user guides that help technical teams and business leaders understand security capabilities and workflows. Currently working on Confluence documentations on vulnerability management, ITSM, incident management, and continuous control monitoring, alongside SEO and AEO content, and technology partner database development.