Human factors in incident response are not a training topic at the edge of the plan. They shape whether an alert is escalated, whether evidence is preserved, whether containment is safe and whether the business receives a clear decision. In 2026, response teams also work across cloud services, identity providers, outsourced operations and automated security tooling. The practical question is not whether people make mistakes. It is whether the response system makes the right action easier under pressure.
A human-centred response program defines decisions, protects handoffs and learns from operating evidence. It gives an analyst with incomplete information at 2 a.m. a workable route to action and escalation.
Why the human element belongs inside the response design
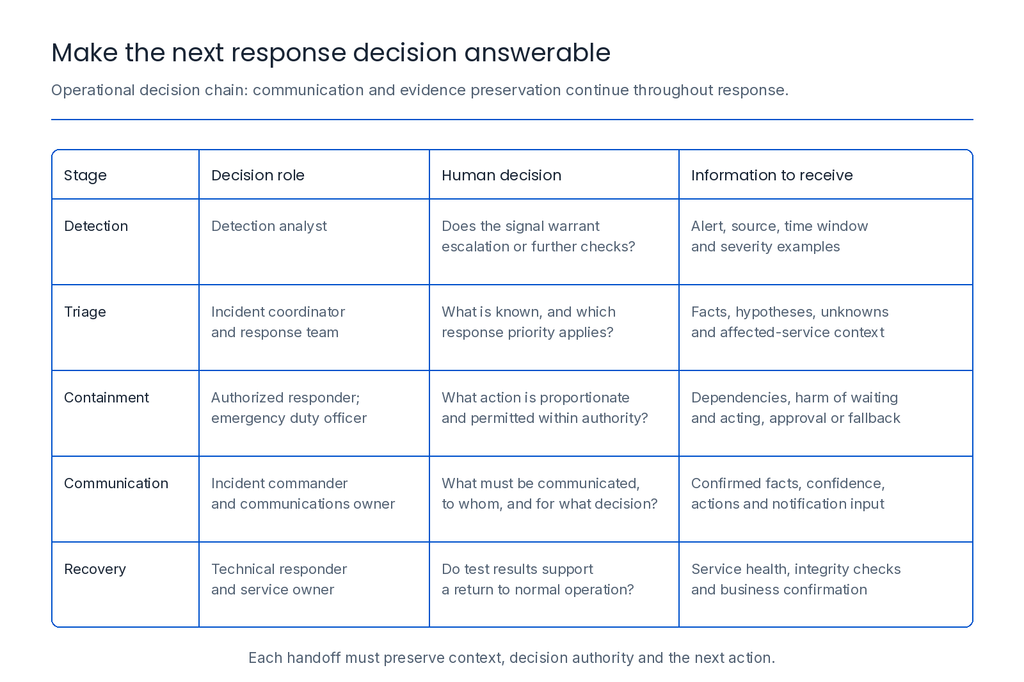
An incident rarely follows one neat path. A detection analyst may see a suspicious sign-in, an identity engineer may revoke sessions, and a service owner may fear an outage. Each decision can change the next person’s options.
NIST finalized SP 800-61 Revision 3 in April 2025. It places incident response within broader cybersecurity risk management and describes Detect, Respond and Recover as the response functions, supported by Govern, Identify, Protect and continuous improvement. The current guidance matters because it treats preparation and learning as part of the operating system around response, not merely a document kept for an audit.
Replace “user error” with a failure condition
Blaming a person produces weak controls. Describe the condition that made the error likely:
– An alert had no severity rule, so the analyst delayed escalation.
– The responder could isolate a production host but could not see its service dependency.
– A contractor’s contact record was stale, so the approval queue stopped moving.
– The incident channel contained several unverified hypotheses with no source labels.
– A playbook required an action that the responder did not have authority to perform.
Address them through decision rights, context, training, guardrails or playbook changes.
Account for fatigue and bias
Fatigue and alert overload reduce the attention available for a critical decision. Rotate demanding duties, arrange relief for prolonged incidents and group related alerts without hiding distinct evidence. Define how a responder requests cover before exhaustion affects the investigation.
Confirmation bias can make a team interpret every new signal as support for its first explanation. During significant decisions, ask what evidence would disprove the current hypothesis. Seniority pressure also matters: provide a clear route for an analyst to challenge an instruction that exceeds authority or creates avoidable service risk.
Design four human decisions before the incident
1. Decide what qualifies for escalation
Write observable triggers and state required evidence and who can reclassify the event.
2. Decide who may contain
Containment authority should reflect the harm of waiting and acting. Pre-authorize bounded actions where appropriate. High-impact actions may need a second reviewer, but define an emergency fallback when waiting would worsen harm. Record who can invoke it and who reviews the decision afterward.
3. Decide what must be communicated
Use a minimum brief covering facts, hypotheses, affected service, time window, actions, decision needed and confidence. Assign an incident commander to coordinate the response and a communications owner to maintain consistent updates.
4. Decide when recovery is safe
Recovery should require a testable condition. Define the service health signal, integrity check and business confirmation needed before returning to normal operation.
Assign evidence and notification responsibilities
Before an incident, assign legal, privacy and compliance contacts to assess regulatory, contractual and customer notification obligations. Maintain a register of applicable triggers, recipients and deadlines, including when each clock starts. Different jurisdictions and commitments can require different notifications; the response team should not assume one universal deadline.
Nominate an evidence custodian to retain relevant logs, timestamps, decision records and collection details with appropriate access restrictions. Record who collected or transferred material and when, supporting chain of custody where necessary. Coordinate preservation with urgent containment so evidence collection does not become an unmanaged delay. Authorized communications should distinguish confirmed facts from unresolved hypotheses.
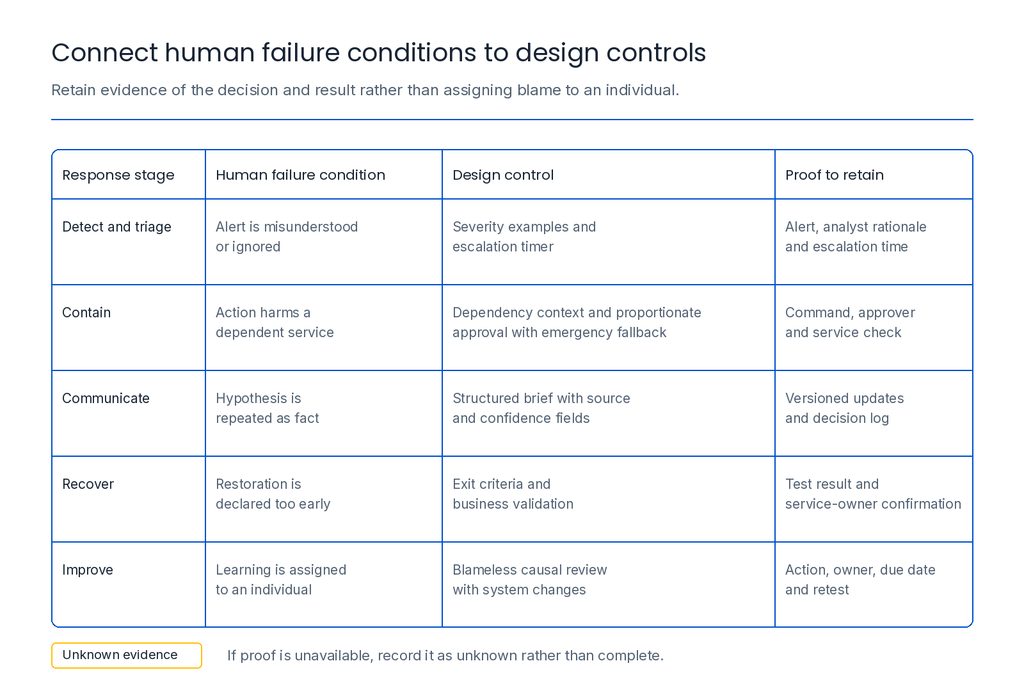
Use a human-risk control map
Map each response stage to the human risk it creates and the control that reduces it.
Response stage
Human failure condition
Design control
Proof to retain
Detect and triage
Alert is misunderstood or ignored
Severity examples and escalation timer
Alert, analyst rationale and escalation time
Contain
Action harms a dependent service
Dependency context and proportionate approval with emergency fallback
Command, approver and service check
Communicate
Hypothesis is repeated as fact
Structured brief with source and confidence fields
Versioned updates and decision log
Recover
Restoration is declared too early
Exit criteria and business validation
Test result and service-owner confirmation
Improve
Learning is assigned to an individual
Blameless causal review with system changes
Action, owner, due date and retest
Work through a response decision under pressure
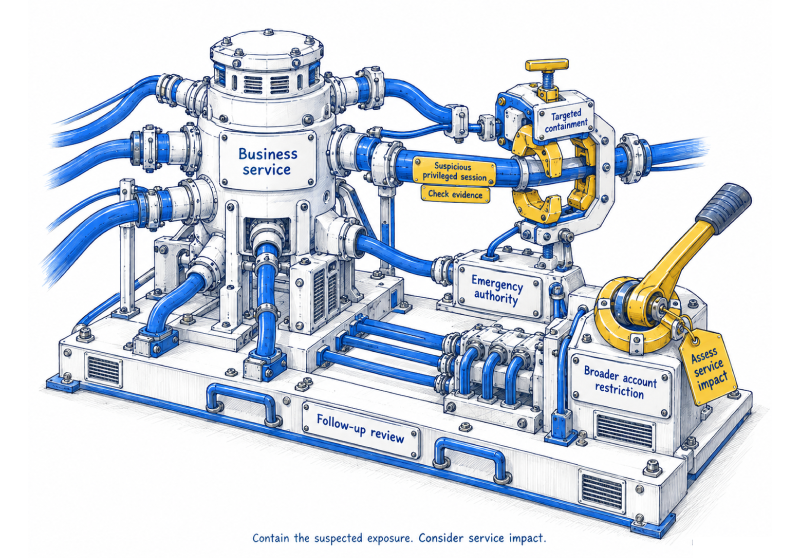
Illustrative scenario: an identity-monitoring alert shows a privileged session from an unfamiliar location. The analyst sees a high-confidence anomaly but cannot confirm whether the user is travelling. The service owner is unavailable. A responder proposes disabling the account immediately.
A weak process asks, “Was the responder right?” A stronger process asks:
1. What is the potential consequence of waiting 15 minutes?
2. What is the consequence of disabling the account?
3. Which evidence can be checked without contacting the user?
4. Who has emergency authority, and how is the action reversed?
5. What must be recorded so the next responder does not repeat the investigation?
One proportionate option may be to preserve available authentication evidence and revoke suspicious sessions under predefined emergency authority while escalating to the identity duty officer. Revocation terminates those sessions; it cannot restore them later. Depending on the identity platform and suspected compromise, reauthentication, credential reset or temporary account restrictions may also be needed. Review restrictions at a defined time and record the reason for acting without the service owner. This is an illustrative decision, not a universal playbook.
Make automation assist judgement, not conceal it
Automation can enrich alerts, open an incident, revoke a session or isolate an endpoint. Its human-risk profile depends on the action, confidence and reversibility. For each automated step, define:
– the signal that triggers it;
– the scope of the action;
– the conditions that pause or require approval;
– the rollback path;
– the record a reviewer will see.
Do not describe an automated action as a human control unless a person can understand and challenge its result. Conversely, do not add an approval step that responders cannot complete within the risk window. The right design is proportionate authority with visible uncertainty.
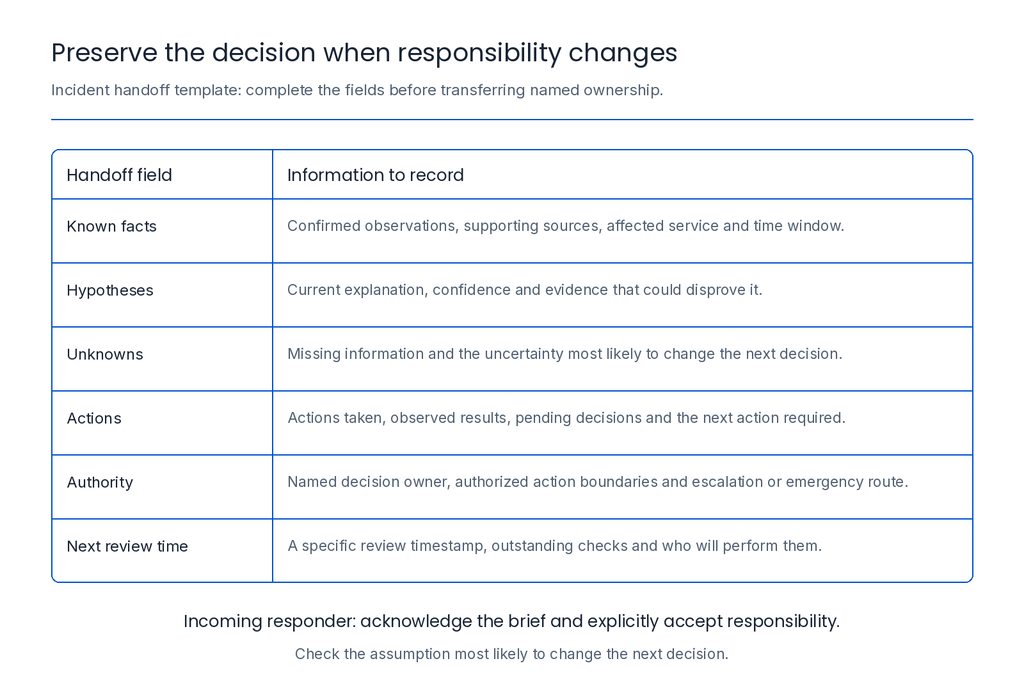
Treat handoffs as control points
Handoffs fail when responsibility changes but context does not. Require the outgoing responder to record the current hypothesis, known facts, unknowns, actions taken, pending decisions and the next review time. The incoming responder should acknowledge the brief and check the assumption most likely to change the next decision. Transfer named ownership explicitly so both shifts know who is acting.
SPOG.AI’s continuous control monitoring connects controls with operational evidence. In an incident-response program, that context can help teams check whether a relevant control or dependency was operating as assumed. Its governance, risk and compliance capability can support a shared view of requirements, control gaps and exceptions across teams. It does not replace incident command, technical judgement or emergency authority.
Learn without turning review into punishment
After recovery, compare the intended response with the actual path. Ask where information, authority, tooling or workload made the safer decision difficult. Produce one or two testable system changes.
NIST’s current incident-response model emphasizes continuous improvement. Apply that guidance operationally by assigning a change, defining its expected result and retesting it in an exercise or live control review. A completed action is not proof that response capability improved.
Measure whether decisions improve
Track time from an escalation trigger to acknowledgment by an authorized responder. Measure handoffs missing required information as a proportion of all reviewed handoffs. Separately track containment actions causing unintended service disruption and improvement actions that pass their planned retest.
Define start and stop points, review periods and severity groupings. Interpret speed alongside harm: faster containment that repeatedly interrupts critical services is not automatically better performance. Use trends to identify which authority rule, staffing arrangement or playbook step needs revision.
Build response systems people can operate
Human factors in incident response are best managed through system design. Define escalation, containment, communication and recovery decisions before the incident. Give responders the context and authority those decisions require. Make automation reversible and handoffs explicit. Then use post-incident learning to change the system, not to search for a convenient person to blame.
The practical test is simple: when an alert becomes a real incident, can the next responder see what is known, what is uncertain, what action is authorized and what evidence will show that the action worked?
Frequently asked questions
They are the workload, communication, authority, decision and interface conditions that affect how people detect, contain and recover from incidents. Managing them means designing response procedures that remain usable under pressure.
They make it harder to identify relevant signals and sustain careful investigation. Provide relief arrangements, prioritize alerts and define when responders should transfer responsibility rather than continue while exhausted.
Keep hypotheses separate from facts and ask which evidence would disprove the leading explanation. Use a second reviewer for consequential decisions when feasible, with an emergency fallback for urgent action.
Follow the documented duty officer or escalation route. A responder with predefined emergency authority can act within its boundaries, recording the justification, service impact and follow-up review rather than waiting indefinitely.
No. Bounded actions can be pre-authorized. High-impact actions may need additional review, but the procedure should specify who can override normal approvals when delay would increase harm.
A terminated session cannot simply be restored. Legitimate users may need to authenticate again, and suspected compromise may require further restrictions or credential changes. Review each action against the identity platform and incident evidence.
Record facts, hypotheses, unknowns, actions, pending decisions, authority and next review time. The incoming responder should acknowledge the brief and explicitly accept responsibility for the next action.
Assigned legal, privacy and compliance contacts assess applicable obligations and coordinate with incident command and communications. Keep jurisdiction-specific and contractual triggers, deadlines and notification records available before an incident occurs.
Defined triggers, bounded scope, approval or pause conditions and visible records help responders assess it. Specify rollback where possible and a recovery procedure where the action cannot be reversed.
Review escalation acknowledgment time, incomplete handoffs, unintended containment disruption and successfully retested improvements. Use defined populations and severity groups so the results support practical decisions rather than reward speed alone.
Technology writer and content strategist with 5+ years of experience, including work for a US-based B2B SaaS client and a cybersecurity solution. I create cybersecurity and GRC content, product documentation, and user guides that help technical teams and business leaders understand security capabilities and workflows. Currently working on Confluence documentations on vulnerability management, ITSM, incident management, and continuous control monitoring, alongside SEO and AEO content, and technology partner database development.